#include <GemmaInferenceEngine.hpp>
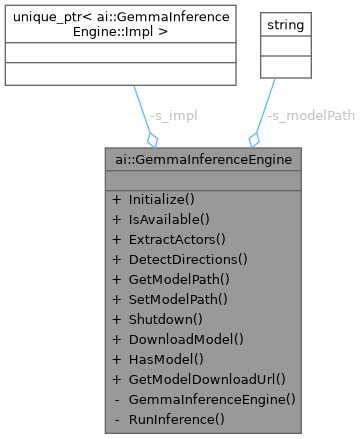
Classes | |
| struct | Impl |
Static Public Member Functions | |
| static bool | Initialize () |
| Initialize the engine. Tries to find/load model, returns false if unavailable. | |
| static bool | IsAvailable () |
| Check if Gemma is available (model found or downloadable) | |
| static GemmaActorResult | ExtractActors (const std::set< std::string > &sampleMessages) |
| static GemmaDirectionResult | DetectDirections (const std::set< std::string > &sampleMessages) |
| static std::string | GetModelPath () |
| Get/set custom model path (default: ~/.logviewer/models/gemma-2b.gguf) | |
| static void | SetModelPath (const std::string &path) |
| static void | Shutdown () |
| Shutdown the engine (frees resources) | |
| static std::string | DownloadModel (const std::string &url, const std::string &filename) |
| static bool | HasModel () |
| Check if model is already downloaded. | |
| static std::string | GetModelDownloadUrl () |
| Get model download URL. | |
Private Member Functions | |
| GemmaInferenceEngine ()=delete | |
Static Private Member Functions | |
| static std::pair< std::string, std::string > | RunInference (const std::string &prompt, int maxTokens=200) |
Static Private Attributes | |
| static std::unique_ptr< Impl > | s_impl |
| static std::string | s_modelPath |
Detailed Description
Gemma 2B inference engine for local actor discovery. Manages model loading, downloading, and inference via llama.cpp.
Constructor & Destructor Documentation
◆ GemmaInferenceEngine()
|
privatedelete |
Member Function Documentation
◆ DetectDirections()
|
static |
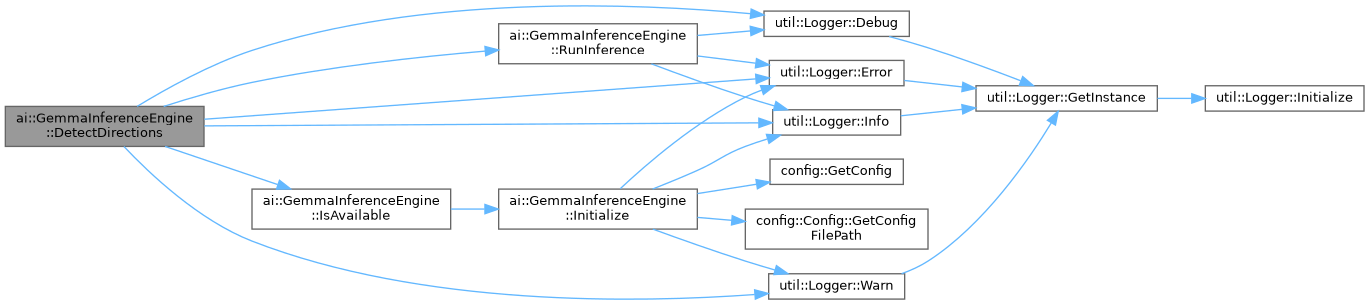
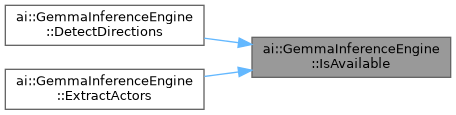
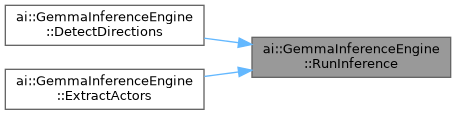
Detect message direction patterns (who sends to whom) using AI analysis. Analyzes log messages to identify sender/receiver fields and keywords. Returns direction pattern with confidence score.
◆ DownloadModel()
|
static |
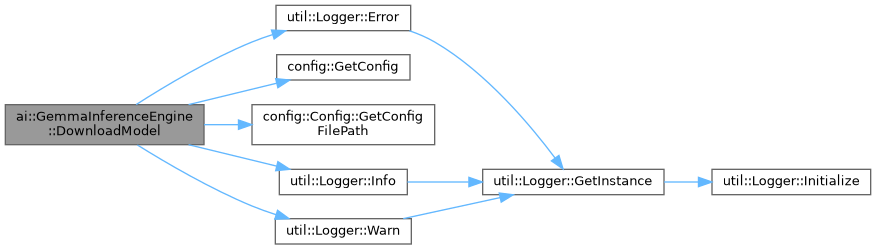
Download model from URL to local path Returns error string (empty if success) Shows progress via logger

◆ ExtractActors()
|
static |
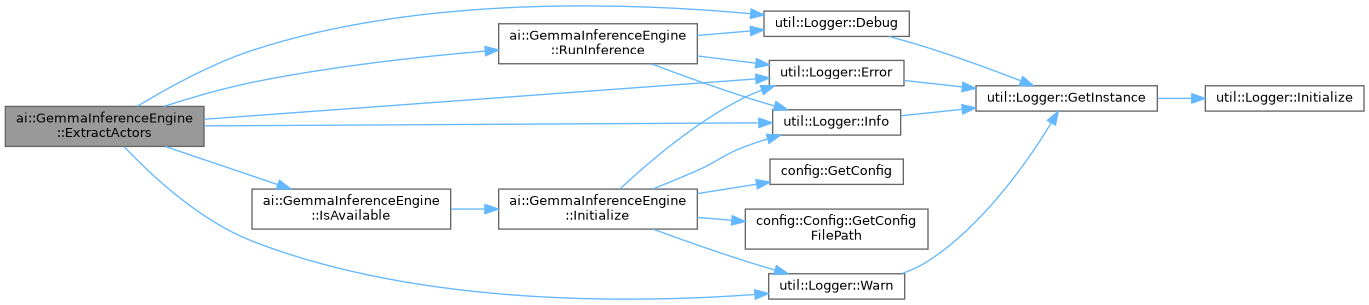
Extract actors from log messages using Gemma 2B. Returns empty result if engine unavailable or inference fails.
◆ GetModelDownloadUrl()
|
static |
Get model download URL.

◆ GetModelPath()
|
static |
Get/set custom model path (default: ~/.logviewer/models/gemma-2b.gguf)

◆ HasModel()
|
static |
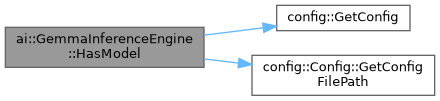
Check if model is already downloaded.

◆ Initialize()
|
static |
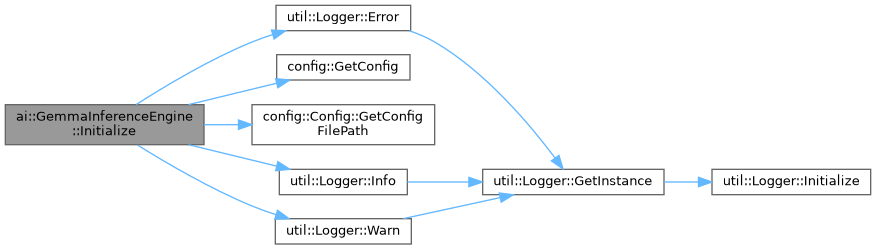
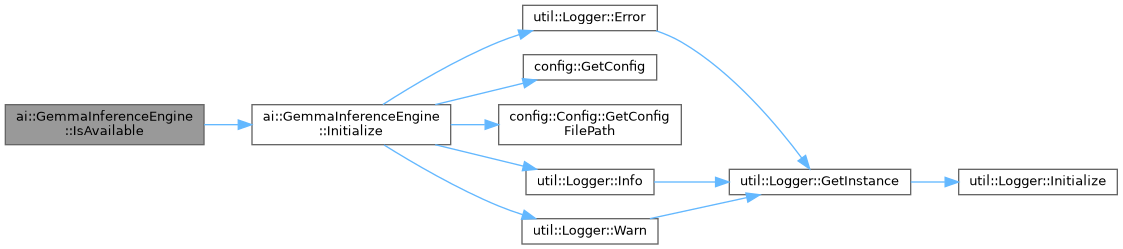
Initialize the engine. Tries to find/load model, returns false if unavailable.
◆ IsAvailable()
|
static |
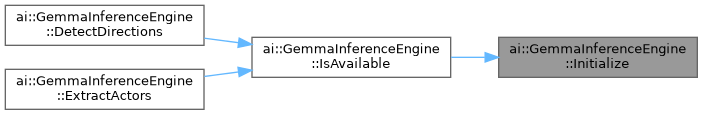
Check if Gemma is available (model found or downloadable)
◆ RunInference()
|
staticprivate |
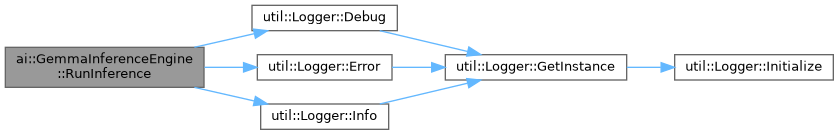
Helper: Run inference on a prompt using the Gemma model Returns pair<output_text, error_message> - if error is empty, output is valid
Static helper: Run inference on a prompt using the Gemma model Returns pair<output_text, error_message> - if error is empty, output is valid
NOTE: This is a stub implementation. The actual inference loop requires:
- llama_tokenize(model, prompt, add_bos, special)
- llama_decode(ctx, batch) for context evaluation
- llama_sample_* functions for token selection
- llama_token_to_piece(model, token, buf, buf_size) for decoding The exact API depends on the llama.cpp version used.
◆ SetModelPath()
|
static |

◆ Shutdown()
|
static |
Shutdown the engine (frees resources)

Member Data Documentation
◆ s_impl
|
staticprivate |
◆ s_modelPath
|
staticprivate |
The documentation for this class was generated from the following files:
- src/application/ai/GemmaInferenceEngine.hpp
- src/application/ai/GemmaInferenceEngine.cpp